AI Prediction Market Scoreboard: 3,625 Kalshi Calls Graded In Public
This page is the running, public grade sheet for every AI model verdict we publish on Kalshi prediction markets. Our panel of AI models has logged 73,925 individual model predictions across 6,559 markets, and 3,625 of those markets have settled and been graded. Every number below is recomputed from the same stored ledger, updated weekly, as of August 23, 2026. Two things up front: the models are frequently wrong, and right now the market's own prices are beating our blend on the graded set. We publish the comparison anyway, every week, because a track record you only show when you are winning is not a track record.
Kalshi event contracts trade on a CFTC-regulated exchange; you must be 18 or older and in an eligible state to participate.
The Quick Answer
On the 1,867 graded markets where we logged a price, our blended model panel scores a Brier of 0.168 against the market's 0.158 on the exact same markets (lower is better; a permanent coin-flip scores 0.250). The market is ahead. When the blend has left the market by 10 points or more, it has been right 89 times and wrong 204 times. The priced category record, the ten biggest documented wins, the five ugliest misses, the one place a single model actually edges the price, and the ten biggest calls still open right now are all below.
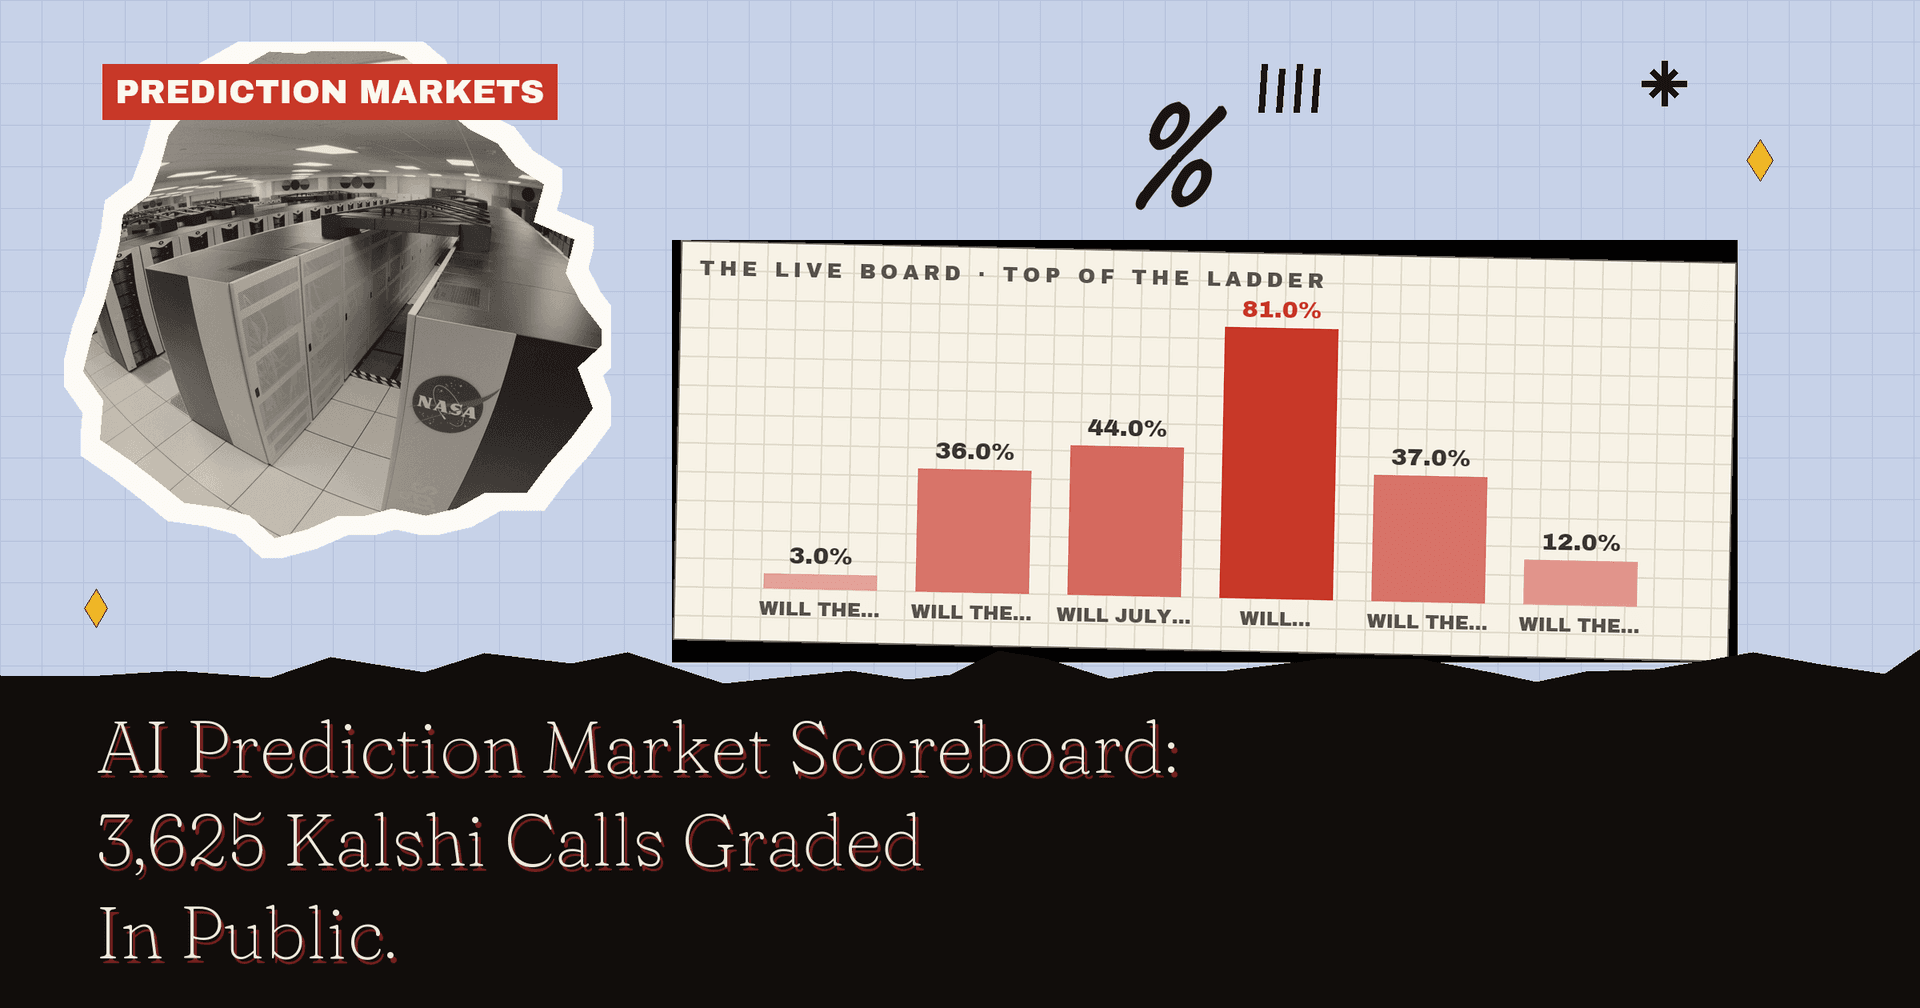
Graded panel calls by market class (the per-run panel-median count, which is stricter than the per-market count in the table below). Rendered from the same ledger; the live totals are the numbers in this article, not the ones baked into the picture.
Stay ahead of the markets.
Daily insights and expert picks on Kalshi, Polymarket, and what's moving markets.
Free forever. Unsubscribe anytime.
The Honesty Block
| Model predictions logged | 73,925 individual verdicts |
| Markets covered | 6,559 distinct Kalshi markets |
| Markets graded | 3,625 settled and scored |
| Still pending | 2,934 markets awaiting settlement |
| Blend Brier (graded, priced) | 0.168 on 1,867 markets |
| Market Brier (same markets) | 0.158 |
| Plain-English verdict | the market is ahead by 0.010 Brier points |
| Numbers as of | August 23, 2026 |
Read that middle pair honestly: the crowd's money is still the best single forecaster we have measured, and any site selling you AI picks without showing you this same comparison is hiding it. The value of the panel is not that it beats the price on average. It is the specific, documented spots where it leaves the price and turns out to be right, and the public record of how often that actually happens.
The Graded Record By Category
One accounting note before the table: 3,625 markets have settled, but only the 1,867 with a market price logged at ask time can be scored against the market, so the other 1,758 (mostly early runs before the price was stored, plus trivial legs) sit out every comparison table on this page. The rows below sum to 1,867.
| Category | Graded (priced) | Blend Brier | Market Brier | Who leads | Most calibrated seat |
|---|---|---|---|---|---|
| Sports | 484 | 0.197 | 0.180 | market ahead | Grok (0.168, n=364) |
| Politics | 25 | 0.195 | 0.161 | market ahead | Gemini Pro (0.091, n=38) |
| Finance | 265 | 0.159 | 0.150 | market ahead | GLM (0.104, n=198) |
| Weather | 317 | 0.154 | 0.143 | market ahead | Grok (0.114, n=361) |
| Entertainment | 36 | 0.062 | 0.041 | market ahead | Grok (0.041, n=121) |
| Mentions | 83 | 0.171 | 0.156 | market ahead | Kimi (0.183, n=88) |
| Crypto | 374 | 0.150 | 0.147 | even | Grok (0.096, n=488) |
| Other | 283 | 0.176 | 0.172 | even | GPT (0.144, n=387) |
A seat needs at least 20 graded markets in a category to appear in the last column, and even then these leads are promising, not proven: at 20 to 90 graded markets a hot streak and real calibration look identical. We will keep grading until the difference is boring.
Where Specific Models Beat The Market
The category table says the blend loses to the price everywhere. So the natural next question, and the one the whole per-niche weighting idea rests on, is whether a particular seat on a particular kind of board has out-forecast the price over a real sample. We cut the ledger into every model-by-category cell with at least 30 graded, priced markets, scored under exactly the same rules as every other table on this page (one product seat per model, trivial legs excluded, one averaged verdict per market), and scored the seat alone against the market on those exact markets. 56 cells qualify.
| Model | Board | Graded | Model Brier | Market Brier | Edge |
|---|---|---|---|---|---|
| Claude Opus | Crypto | 30 | 0.133 | 0.136 | 0.003 |
That is the complete list: 1 of 56 cells. The widest edge is Claude Opus on crypto boards, 30 graded markets, Brier 0.133 against the market's 0.136, a gap of 0.003 Brier points. On a sample that size, that gap is a lead, not a finding.
Here is why we show the strict cut and not the flattering one. Score the same question loosely, with every run variant of a model counted as its own seat, the price taken row by row, and the trivial legs left in, and 9 of 89 cells come out ahead of the market. The typical edge in that version is 0.0009 Brier points, and the largest is 0.0037, which is the kind of margin that appears and disappears with a week of settlements. Split the seats and skip the filter and the panel looks like it has found cracks everywhere; collapse the seats and apply the filter and almost all of them close. We would rather print the version that closes. The per-niche weighting on our live boards still leans on the seat with the best record in each market class, because a seat that matches the price is a better input than one that trails it, but nobody should read this table as the panel beating the market in any niche yet. When a cell holds its edge past a few hundred graded markets, it will say so here first.
Receipts: The 10 Biggest Wins
A win here has a strict definition: the blend diverged from the market price by 10 points or more, we logged it before settlement, and the market settled on our side, on a market that actually traded (a divergence against an untraded book's phantom mid is not a win against anyone, so those are dropped here). Sorted by the size of the divergence. One disclosure: most of these divergences come from the fast-settling calibration boards we grade daily (crypto, weather, mentions), where the panel takes hundreds of small swings; the long-dated article boards settle much more slowly and are underrepresented so far. And some game markets were asked while the game was in play, so the logged price reflects the live score at that moment; the blend is scored against that same moment, never against a pregame number it did not see.
| Market | Market price | Our blend | Settled | Divergence |
|---|---|---|---|---|
| Will the maximum temperature be 92-93° on Aug 9, 2026? | 78c | 3% | NO | 75 pts |
| Will the high temp in NYC be 89-90° on Aug 7, 2026? | 86c | 36% | NO | 50 pts |
| Will July 14 be the day with the most transit calls through the Strait of Hormuz (7/13 - 7/19)? | 90c | 44% | NO | 46 pts |
| Will Trump say 'MAGA / Make America Great Again' during the White House Correspondents Dinner (Jul 24, 2026)? | 39c | 81% | YES | 42 pts |
| Will the high temp in NYC be 79-80° on Jul 20, 2026? | 77c | 37% | NO | 40 pts |
| Will the minimum temperature be >83° on Aug 1, 2026? (84° or above) | 51c | 12% | NO | 39 pts |
| Will Trump say 'IQ / Genius' during the White House Correspondents Dinner (Jul 24, 2026)? | 28c | 64% | YES | 36 pts |
| Will Trump say 'Kamala' during the White House Correspondents Dinner (Jul 24, 2026)? | 31c | 67% | YES | 36 pts |
| Miami vs San Luis: Total Goals: Over 6.5 goals scored | 58c | 23% | NO | 35 pts |
| Toronto vs Philadelphia Winner? (Philadelphia) | 84c | 50% | NO | 34 pts |
The 5 Biggest Misses
The misses stay on the page permanently. They are the reason you can trust the wins.
One class of row is excluded from every table on this page: 785 markets that were already priced at 95¢ or above (or 5¢ or below) at the moment the panel was asked. Those are news-timing artifacts — the market had absorbed an announcement the panel's data card predates — and grading them as divergences would manufacture fake wins and fake misses alike. Since August 19 the pipeline refuses to run a panel on an already-decided board; this exclusion applies the same standard to older rows.
| Market | Market price | Our blend | Settled | Divergence |
|---|---|---|---|---|
| Barcelona vs Macara Winner? (Macara) | 90c | 23% | YES | 67 pts |
| Will the minimum temperature be 67-68° on Aug 9, 2026? | 68c | 2% | YES | 66 pts |
| Palmeiras vs Internacional: Total Goals: Over 1.5 goals scored (leg 2) | 6c | 68% | NO | 62 pts |
| Will the minimum temperature be >83° on Aug 10, 2026? (84° or above) | 69c | 10% | YES | 60 pts |
| Will OKSavingsBank BRION win the Gen.G vs. OKSavingsBank BRION League of Legends match? | 80c | 24% | YES | 56 pts |
The ledger's ugliest entry, in plain terms: the panel put 23% on “Barcelona vs Macara Winner? (Macara)” while the market sat at 90c, and the market was right. That row is exactly why the “Will the maximum temperature be 92-93° on Aug 9, 2026?” win above means something.
Live Calls: The Biggest Open Divergences Right Now
These are the largest gaps between a published model blend and the live Kalshi price at this scoreboard's last refresh (live prices as of August 23, 2026). Each one is a standing claim that will be graded onto this page when it settles. A positive gap means the blend is higher than the price. The link goes to the article that covers that market's whole board (an award race, a rate-cut ladder), which is why its title can name a different leg than the row.
| Market | Our blend | Live price | Gap | Settles | Full board |
|---|---|---|---|---|---|
| Will the Fed cut rates 0 times? (Exactly 0 cuts) | 27% | 88c | -61 pts | 2026-12-31 | our board article |
| Will A'ja Wilson win MVP? | 25% | 86c | -61 pts | 2026-12-31 | our board article |
| Will Kevin McGonigle win AL ROTY? | 40% | 84c | -44 pts | 2026-12-31 | our board article |
| Will Apple Inc. release iPhone 18 before Jan 1, 2027? | 58% | 14c | +43 pts | 2027-01-01 | our board article |
| Will Napheesa Collier win MVP? | 44% | 1c | +43 pts | 2026-12-31 | our board article |
| 2026 Game of the Year? (Grand Theft Auto VI) | 29% | 66c | -37 pts | 2026-12-10 | our board article |
| Will Apple Inc. release iPhone 18 before Oct 1, 2026? (Before October) | 44% | 8c | +37 pts | 2027-01-01 | our board article |
| Will JJ Wetherholt win NL ROTY? | 23% | 50c | -26 pts | 2026-12-31 | our board article |
| Will Shohei Ohtani win NL MVP? | 15% | 38c | -23 pts | 2026-12-31 | our board article |
| Insidious: Out of the Further Rotten Tomatoes score? (Above 65) | 12% | 1c | +11 pts | 2026-08-24 | our board article |
How The Scoreboard Works
- Price-blind protocol. Each model in the panel is asked for a probability before it is shown the market price, working from a fetched data card of verified facts (rosters, ledgers, filings, schedules). Cards are fetched, never hand-written.
- Revision rounds. Panels run structured revision rounds; the stored verdict is the one the article shipped with, timestamped at ask time, before settlement. Every prediction on this page was published before the market settled.
- Grading rule. Brier score: the squared gap between the stated probability and the outcome (YES=1, NO=0), averaged. Zero is perfect, 0.250 is a permanent coin-flip, lower is better. The market is scored on the price logged at the same moment the models were asked, on the exact same markets.
- Trivial legs are excluded. Markets where the model said 3% or less, the price was 3c or less, and the outcome was NO are dropped from every scored table. Predicting that a 1c longshot loses is not skill, and leaving those rows in would flatter every number on this page.
- The universe, pinned. Every stored panel verdict row with a probability, averaged per model per market across runs; the blend is the equal-weight mean of the model seats. Rows stay in the database forever; nothing is retroactively removed from the ledger.
- Refresh cadence. A weekly job recomputes this entire page from the ledger and republishes it only when new markets have been graded. The page you are reading was generated by that job, not edited by hand.
A Worked Example: How One Call Gets Graded
Take the top win above: “Will the maximum temperature be 92-93° on Aug 9, 2026?” The blend said 3% while the market priced it at 78c, and it settled NO. Score both against the outcome (0): the blend takes (0.03 minus 0) squared = 0.001, the market takes (0.78 minus 0) squared = 0.608. Lower is better, so the blend won this market by 0.607 Brier points. Every graded market on this page went through exactly that arithmetic, and the headline numbers are the averages.
Every individual model verdict article carries its own market table, and each one feeds this scoreboard. If you want the methodology in action, start with the prediction markets hub or read how prediction markets work and how accurate prediction markets are. And when a sports call points you at a sportsbook number instead of an event contract, shop it first on the live odds screen.
The models are frequently wrong, the market is currently outscoring the blend, and this page exists so you never have to take our word for either claim.
Scoreboard recomputed from the graded verdict ledger as of August 23, 2026.
More on this: AI Models vs Prediction Markets: The Graded Scoreboard · Where Does Bitcoin End 2026? Kalshi's Price-Band Odds · 2026 Governor Races: Every Kalshi Board We Track · Who Wins The 2027 NBA Title? Kalshi Championship Odds · NFL 2026 on Kalshi: Every Board We Track